The cheapest current API models are GPT-6 Luna and Claude Haiku 5.5, both at $0.10 per million input tokens and $0.50 per million output tokens. The mid tier, GPT-6.1 Sol and Claude Sonnet 5.5, costs $2 / $10, and the top models, GPT-6 Astra and Claude Fable 5.1, cost $10 / $50. Gemini 4 Argon is $2 / $10 today but doubles to $4 / $20 on December 1, 2026.
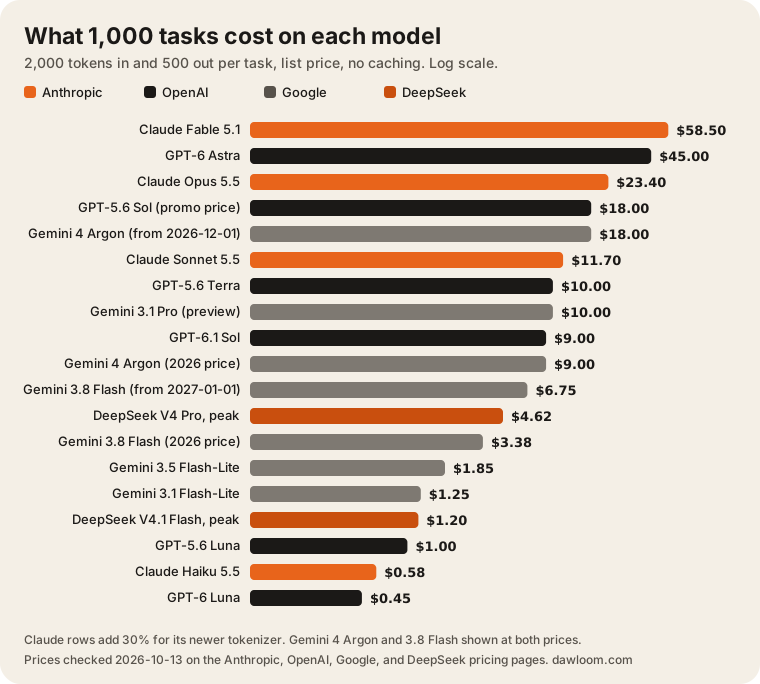
For one task of 2,000 input and 500 output tokens, that range runs from $0.45 to $58.50 per 1,000 tasks. Every price on this page was read from the official pricing pages of OpenAI, Anthropic, Google, and DeepSeek on 2026-10-13.
Who this is for: developers and product owners choosing a model for a feature, or checking a cost estimate. Who should look elsewhere: if you buy ChatGPT, Claude, or Gemini as seats for staff, this is the wrong price list. Seat plans are priced per user, not per token. If you want the cost per user of a whole feature, use our AI feature cost calculator, which reads the same prices.
The full price table
The table below is built from the same price file as our calculators, so the numbers here and in the tools always match. “1,000 tasks” is the cost of 1,000 calls with 2,000 input tokens and 500 output tokens at the standard rate, with no caching.
| Model | Input | Cached input | Cache write | Output | Batch in / out | Long prompts | 1,000 tasks | Scheduled change |
|---|---|---|---|---|---|---|---|---|
| Claude Fable 5.1Anthropic | $10 | $0.25 | $12.50 | $50 | $5 / $25 | Flat to 1M | $58.50 | |
| Claude Opus 5.5Anthropic | $4 | $0.20 | $5 | $20 | $2 / $10 | Flat to 1M | $23.40 | |
| Claude Sonnet 5.5Anthropic | $2 | $0.10 | $2.50 | $10 | $1 / $5 | Flat to 1M | $11.70 | |
| Claude Haiku 5.5Anthropic | $0.10 | $0.01 | $0.125 | $0.50 | $0.05 / $0.25 | Over 100K: $0.50 / $2.50 | $0.58 | |
| GPT-6 AstraOpenAI | $10 | $1 | $12.50 | $50 | $5 / $25 | Over 272K: 2x in, 1.5x out | $45.00 | |
| GPT-6.1 SolOpenAI | $2 | $0.10 | $2.50 | $10 | $1 / $5 | Over 272K: 2x in, 1.5x out | $9.00 | |
| GPT-6 LunaOpenAI | $0.10 | $0.01 | $0.125 | $0.50 | $0.05 / $0.25 | Over 272K: 2x in, 1.5x out | $0.45 | |
| GPT-5.6 Sol (promo price)OpenAI | $4 | $0.40 | $5 | $20 | $2 / $10 | Over 272K: 2x in, 1.5x out | $18.00 | Promo price "at least through November 21, 2026" |
| GPT-5.6 TerraOpenAI | $2 | $0.20 | $2.50 | $12 | $1 / $6 | Over 272K: 2x in, 1.5x out | $10.00 | |
| GPT-5.6 LunaOpenAI | $0.20 | $0.02 | $0.25 | $1.20 | $0.10 / $0.60 | Over 272K: 2x in, 1.5x out | $1.00 | |
| Gemini 4 Argon (2026 price)Google | $2 | $0.10 | No write fee | $10 | $1 / $5 | Flat to 1M | $9.00 | Doubles on Dec 1, 2026 |
| Gemini 4 Argon (from 2026-12-01)Google | $4 | $0.20 | No write fee | $20 | $2 / $10 | Flat to 1M | $18.00 | From Dec 1, 2026 |
| Gemini 3.1 Pro (preview)Google | $2 | $0.20 | No write fee | $12 | $1 / $6 | Over 200K: $4 / $18 | $10.00 | Preview model |
| Gemini 3.8 Flash (2026 price)Google | $0.75 | $0.075 | No write fee | $3.75 | $0.375 / $1.875 | Flat | $3.38 | Doubles on Jan 1, 2027 |
| Gemini 3.8 Flash (from 2027-01-01)Google | $1.50 | $0.15 | No write fee | $7.50 | $0.75 / $3.75 | Flat | $6.75 | From Jan 1, 2027 |
| Gemini 3.5 Flash-LiteGoogle | $0.30 | $0.03 | No write fee | $2.50 | $0.15 / $1.25 | Flat | $1.85 | |
| Gemini 3.1 Flash-LiteGoogle | $0.25 | $0.025 | No write fee | $1.50 | $0.125 / $0.75 | Flat | $1.25 | Shuts down May 7, 2027 |
| DeepSeek V4.1 Flash (deepseek-flash)DeepSeek, peak hours | $0.30 | $0.006 | Not listed | $1.20 | No Batch. Off-peak is half: $0.15 / $0.60 | Flat to 1M | $1.20 | DeepSeek pricing |
| DeepSeek V4 Pro (deepseek-v4-pro)DeepSeek, peak hours | $1.32 | $0.044 | Not listed | $3.96 | No Batch. Off-peak is half: $0.66 / $1.98 | Flat to 1M | $4.62 | DeepSeek pricing |
How to read the columns:
- Cached input is what you pay when the start of your prompt matches a recent call. It is 5% of the input price on Claude Opus 5.5 and Sonnet 5.5, 2.5% on Fable 5.1, and 5% to 10% on OpenAI and Google models. Prompts below a minimum length are not cached: 512 tokens on current Claude models, 1,024 on OpenAI, and 4,096 on Gemini 4 Argon and 3.8 Flash.
- Cache write is a one-time premium to store a prefix. Anthropic charges 1.25x the input price for a 5-minute cache. OpenAI lists a cache write price for its GPT-6 and GPT-5.6 models. Google charges no write premium, but bills explicit cache storage by the hour, for example $0.50 per million tokens per hour on Gemini 3.8 Flash.
- Batch halves the input and output price on every Anthropic, OpenAI, and Google model in the table, if you can wait for the result. DeepSeek has no Batch tier but charges half price off-peak.
- Long prompts is where most tables go wrong. OpenAI’s model pages say “Prompts with more than 272K input tokens are priced at 2x input and cache rates and 1.5x output for the full request.” Claude Haiku 5.5 jumps to $0.50 / $2.50 above 100,000 tokens. Gemini 3.1 Pro Preview goes to $4 / $18 above 200,000. Claude Fable 5.1, Opus 5.5, and Sonnet 5.5 stay flat to 1 million tokens.
What 1,000 tasks cost, cheapest first
| Model | Provider | 1,000 tasks | At list price, same token count |
|---|---|---|---|
| GPT-6 Luna | OpenAI | $0.45 | |
| Claude Haiku 5.5 | Anthropic | $0.58 | $0.45 |
| GPT-5.6 Luna | OpenAI | $1.00 | |
| DeepSeek V4.1 Flash (deepseek-flash), peak | DeepSeek | $1.20 | |
| Gemini 3.1 Flash-Lite | $1.25 | ||
| Gemini 3.5 Flash-Lite | $1.85 | ||
| Gemini 3.8 Flash (2026 price) | $3.38 | ||
| DeepSeek V4 Pro (deepseek-v4-pro), peak | DeepSeek | $4.62 | |
| Gemini 3.8 Flash (from 2027-01-01) | $6.75 | ||
| GPT-6.1 Sol | OpenAI | $9.00 | |
| Gemini 4 Argon (2026 price) | $9.00 | ||
| GPT-5.6 Terra | OpenAI | $10.00 | |
| Gemini 3.1 Pro (preview) | $10.00 | ||
| Claude Sonnet 5.5 | Anthropic | $11.70 | $9.00 |
| GPT-5.6 Sol (promo price) | OpenAI | $18.00 | |
| Gemini 4 Argon (from 2026-12-01) | $18.00 | ||
| Claude Opus 5.5 | Anthropic | $23.40 | $18.00 |
| GPT-6 Astra | OpenAI | $45.00 | |
| Claude Fable 5.1 | Anthropic | $58.50 | $45.00 |
Two things the per-token prices hide:
- Claude counts more tokens. Anthropic’s pricing page says Claude 4.7 and later models use a tokenizer that “produces approximately 30% more tokens for the same text.” So Claude Sonnet 5.5 and GPT-6.1 Sol share a $2 / $10 list price, but the same task costs about $11.70 on Sonnet and $9 on Sol. We add that 30% in the task column. Measure your own prompts before you trust it.
- Thinking tokens are output. Google labels its output price “including thinking tokens.” OpenAI and Anthropic bill reasoning tokens as output too. A model that thinks for 2,000 tokens before a 500-token answer costs five times the output in our example. Our task shape assumes no thinking.
The three tiers, in one line each
| Tier | Models | Input / output per 1M | Use it for |
|---|---|---|---|
| Top | Claude Fable 5.1, GPT-6 Astra | $10 / $50 | Long agent runs and hard reasoning, after a cheaper model fails your tests |
| Mid | Claude Sonnet 5.5, GPT-6.1 Sol, Gemini 4 Argon (to Nov 30) | $2 / $10 | Most product features: drafting, support replies, agents with tools |
| Cheap | Claude Haiku 5.5, GPT-6 Luna | $0.10 / $0.50 | Extraction, classification, routing, high volume |
Claude Opus 5.5 ($4 / $20) sits between top and mid. Anthropic’s models page says “start with Claude Opus 5.5 for most workloads.” OpenAI’s says “If you’re not sure where to start, use GPT-6 Astra.” Both vendors start you high. On price, that is a 4x to 20x difference over the mid tier, so test the cheaper model first. Our decision guide to choosing a model walks through that test.
DeepSeek: peak and off-peak
DeepSeek is the only provider here with time-of-day pricing. Its page says “Off-peak rates are half of the peak rates. Peak hours are 01:00 - 04:00 and 06:00 - 10:00 UTC, Monday through Friday, excluding Chinese public holidays.”
| Model | Peak in / out | Off-peak in / out | Cache hit, peak |
|---|---|---|---|
deepseek-flash (V4.1 Flash) |
$0.30 / $1.20 | $0.15 / $0.60 | $0.006 |
deepseek-v4-pro |
$1.32 / $3.96 | $0.66 / $1.98 | $0.044 |
DeepSeek’s cache hit price is 2% of its peak input price, the lowest ratio in this table. The old model names deepseek-v4-flash and deepseek-v4-flash-vision-exp are now routed to V4.1 Flash and billed at the Flash price, per its change log. We include DeepSeek for price. We have not checked its data terms, so read them before you send it customer data.
Price changes log
| Date | Change | Source |
|---|---|---|
| 2026-09-10 | DeepSeek released V4.1 Flash and cut API prices. Old V4 Flash names now bill at the Flash price | DeepSeek change log |
| 2026-10-13 | Gemini 4 Argon became generally available at $2 / $10 “through November 30, 2026” | Gemini release notes |
| Until at least 2026-11-21 | GPT-5.6 Sol at its promotional $4 / $20. OpenAI says it “is available at least through November 21, 2026” | OpenAI pricing |
| 2026-12-01 | Gemini 4 Argon doubles to $4 / $20, cache to $0.20 | Gemini pricing |
| 2027-01-01 | Gemini 3.8 Flash and 3.6 Flash double to $1.50 / $7.50 | Gemini pricing |
Our Gemini price increase guide shows what the two Gemini changes do to three real workloads. Some older models are also shutting down, which can force a price change on its own date. The AI model retirement calendar lists every date.
Why other pricing tables disagree
We read the top results for “LLM API pricing comparison” before writing this. Several still list Claude Opus 4 at $15 / $75 as a current model. One October roundup is careful and links its sources, but it doesn’t name Gemini 4 Argon or its December price. Most tables skip cache writes, the 272K and 100K price steps, and the cost of an actual task. Prices change often enough that any table without a check date should be treated as old.
We update this page monthly and on every model launch, starting from our shared price file.
FAQ
What is the cheapest AI API right now?
At list price, GPT-6 Luna and Claude Haiku 5.5, both $0.10 input and $0.50 output per million tokens, checked 2026-10-13. Claude counts about 30% more tokens for the same text, so GPT-6 Luna is a little cheaper per task. DeepSeek V4.1 Flash off-peak ($0.15 / $0.60) is close behind.
How much does the Claude API cost compared with OpenAI?
At the same tier, list prices match. Sonnet 5.5 and GPT-6.1 Sol are both $2 / $10, Haiku 5.5 and GPT-6 Luna are both $0.10 / $0.50, and Fable 5.1 and GPT-6 Astra are both $10 / $50. Per task, Claude costs about 30% more because of its tokenizer, but Claude’s mid and top models don’t charge extra for prompts over 272,000 tokens.
Is Gemini cheaper than GPT and Claude?
For now, Gemini 4 Argon matches GPT-6.1 Sol and Sonnet 5.5 at $2 / $10. From December 1, 2026, it costs twice as much. Gemini 3.8 Flash at $0.75 / $3.75 is cheaper than the mid tier but costs more than GPT-6 Luna and Haiku 5.5, and it doubles on January 1, 2027.
Does caching really cut the bill?
Yes, when the start of your prompt repeats. On Claude Sonnet 5.5 a cache hit costs $0.10 per million tokens against $2 for fresh input. Our post on why MCP servers use so many tokens shows how much of a typical prompt repeats on every call.
How do I turn token prices into a price for my product?
Work out the cost per user per month, then add Stripe fees and infra. Our AI cost per user guide does the first step, and how to price an AI SaaS and the margin calculator do the rest.
If you’d rather we pick and test the model for your product, that is part of our AI integration work. Our fixed prices are on the pricing page.