
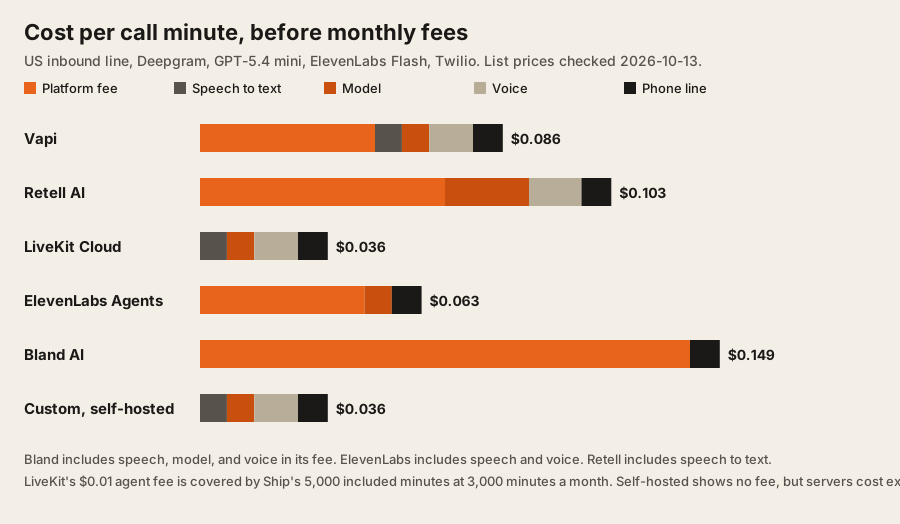
For the same US booking line, Vapi costs about $0.086 a call minute and Retell about $0.103, at list prices we checked on 2026-10-13. LiveKit Cloud comes to about $0.036 a minute plus a $50 monthly plan, and building on open-source code yourself removes the platform fee but adds servers and upkeep.
The model barely moves the bill. The platform fee does. Vapi’s hosting fee is $0.05 a minute and Retell’s is $0.055, which is more than speech to text, the model, the voice, and the phone line cost together.
Who this is for: a business choosing a platform for an AI receptionist, booking line, or intake line, or a developer pricing one for a client. Who should look elsewhere: if you want a finished product with no building at all, look at a hosted answering product instead. All four options here need someone to write prompts, connect tools, and test calls.
How we checked
We read each vendor’s own pricing page on 2026-10-13 and built one scenario on all of them: inbound US calls on a Twilio local number, Deepgram Nova-3 for speech to text, GPT-5.4 mini as the model, and ElevenLabs Flash as the voice wherever the platform lets you pick. Retell sells the model and voice at its own per-minute rates, so we used its listed rate for GPT 5.4 mini and its platform voices.
Model tokens are our assumption, not a measurement: 6 model turns a minute, 2,500 input and 60 output tokens a turn, half the input from the prompt cache. You can change every one of these in our voice agent cost calculator, which uses the same price file as this post. Our guide to AI phone agent cost per month walks through that calculator, where the money goes, and what it leaves out.
We did not run a latency test. The latency numbers below are each vendor’s own claim.
Cost per minute, part by part
| Per minute, list price | Vapi | Retell AI | LiveKit Cloud | Custom, self-hosted |
|---|---|---|---|---|
| Platform fee | $0.05 | $0.055 | $0.01 after included minutes | $0 |
| Speech to text (Deepgram Nova-3) | $0.0077, passed through | Included | $0.0077 | $0.0077 |
| Model (GPT-5.4 mini) | about $0.008 at OpenAI token prices | $0.024, Retell’s rate | about $0.008 | about $0.008 |
| Voice (ElevenLabs Flash, 40% talk time) | about $0.0125 | $0.015 for Retell platform voices, $0.04 for ElevenLabs Flash | about $0.0125 | about $0.0125 |
| Phone line (Twilio US local inbound) | $0.0085 | $0.0085, or $0.015 on a Retell number | $0.0085, or $0.01 on a LiveKit number | $0.0085 |
| Usage per minute | $0.086 | $0.103 | $0.036 | $0.036 |
| Monthly fee in this scenario | $0 | $0 | $50 (Ship, 5,000 minutes) | $100 for servers (our placeholder) |
| At 3,000 minutes a month | $261 | $309 | $161 | $211 |
Sources, all checked 2026-10-13: Vapi pricing, Retell pricing, LiveKit pricing, Deepgram, ElevenLabs API, Twilio US voice, and OpenAI for GPT-5.4 mini at $0.75 in and $4.50 out per 1M tokens. The monthly totals add one Twilio number at $1.15.
Two other hosted options, for reference, in the same scenario: ElevenLabs Agents comes to $290 on its Pro plan, and Bland AI to $447.
What each one is, in the vendors’ words
Vapi
Vapi is a hosted platform where you pick each part. Its page lists “$0.05/min Vapi hosting”, with providers charged “at cost” and “Provider costs with no markup”. Without a plan you get 4 concurrent calls. Core is “$29 / month” for 10, and more lines are “$10 / line / month” (Vapi).
Vapi’s own estimate for 1,000 minutes with Deepgram, OpenAI, and ElevenLabs is $82 to $129 a month. Our scenario comes to $88 at 1,000 minutes, inside that range.
Pick it when you want to try different speech, model, and voice providers quickly and keep their list prices.
Retell AI
Retell bundles speech to text into a “Retell Voice Infra $0.055/minute” fee and sells the model and voice per minute. GPT 5.4 mini is “$0.024/minute”, platform voices are “$0.015/minute”, and ElevenLabs Flash is “$0.040/minute”. Retell numbers are “$2.00/month”, and “No Charge for Sip Trunking/Custom Telephony”. It includes “20 Free Concurrent Calls” and tracks each call “to the nearest second” (Retell).
Retell’s page calls its range “$0.07-$0.31 / min for AI Voice Agents”. Its own calculator default is $0.11 a minute.
Pick it when you want one bill with per-minute model prices you can read up front, and 20 concurrent calls without a plan.
LiveKit Cloud
LiveKit is open-source realtime infrastructure plus a hosted cloud. On LiveKit Cloud, the “Agent session” is “$0.0100/min”. Build is free with 1,000 minutes, Ship starts at “$50/mo” with 5,000 minutes, and Scale at “$500/mo” with 50,000. Phone numbers are “$1.00/month per number” after one free number, and US local inbound is “$0.01 per min” after the included minutes (LiveKit).
LiveKit’s own calculator default comes to “$0.0479/min” with LiveKit Inference for speech, model, and voice, plus observability and telephony. It is higher than our $0.036 mainly because it adds $0.01 a minute for observability.
Pick it when you have developers, expect real volume, and want the option to move to self-hosting later without rewriting the agent.
Custom, self-hosted
The LiveKit Agents framework is open source, and Pipecat is another common choice. You run the agent and media servers yourself, connect a SIP trunk, and pay providers directly. There is no platform fee. The cost moves to servers, monitoring, and the people who keep it running, which a price page can’t show. The $100 a month in our table is a placeholder, not a quote.
Pick it when you run thousands of minutes a month, steady enough that 5 cents a minute is real money, and you already have someone who can be on call for it.
Latency, as each vendor states it
These are marketing claims, not tests. We have not measured them.
- Vapi: “Scale up to millions of calls with sub-500ms latency” (vapi.ai).
- Retell: “With ~600ms latency, conversations stay smooth and fluent” (retellai.com).
- LiveKit: “Deliver voice and video worldwide in under 250ms” (LiveKit pricing). That is a network figure, not the time until the agent answers.
Delay in a voice agent comes mostly from the model and the voice, which you can pick on Vapi, LiveKit, and a custom build. Our explainer on what a realtime voice agent consists of walks through where the time goes.
Which one to pick
| Your situation | Pick |
|---|---|
| Testing an idea, under 1,000 minutes a month | Vapi or Retell. The cost gap is about $15 a month |
| A non-technical team that wants one bill and read-up-front rates | Retell |
| You want to mix providers and keep their list prices | Vapi |
| A developer team, a few thousand minutes or more | LiveKit Cloud |
| Tens of thousands of steady minutes and an on-call engineer | Custom on LiveKit Agents or Pipecat |
| You want one fixed price that covers speech, model, and voice | Bland AI, at $0.14 a minute plus telephony |
FAQ
Is Vapi cheaper than Retell?
In our scenario, yes: about $0.086 a minute against $0.103. The gap comes from Retell’s per-minute model rate. With Retell’s cheapest listed model, GPT 5 mini at $0.008 a minute, the two land close together.
What does LiveKit cost for a voice agent?
The agent session is $0.01 a minute after the plan’s included minutes. Ship is $50 a month with 5,000 minutes. You also pay for speech to text, the model, the voice, and the phone line, through LiveKit Inference or your own provider keys.
Is it cheaper to build a voice agent myself?
The running cost per minute is lower, about $0.036 in our scenario with no platform fee. But building, testing, and running it cost more. It makes sense at high, steady volume with someone to look after it.
Which voice agent platform has the lowest latency?
We haven’t tested it, and we wouldn’t trust anyone’s single number. Vapi claims under 500ms, Retell about 600ms. Test your own call flow with your chosen model and voice before you commit.
Dawloom builds AI agents, including phone agents with booking tools and a handoff to a person, from a written scope, billed hourly or by milestone. For the running bill with your own numbers, use the voice agent cost calculator. Before you build one, read how to make an AI agent wait for human approval, and if you are comparing builders, our list of AI agent development companies for small businesses. For agent code outside voice, see OpenAI Agents SDK vs Claude Agent SDK.